The new release
expands clinical coverage
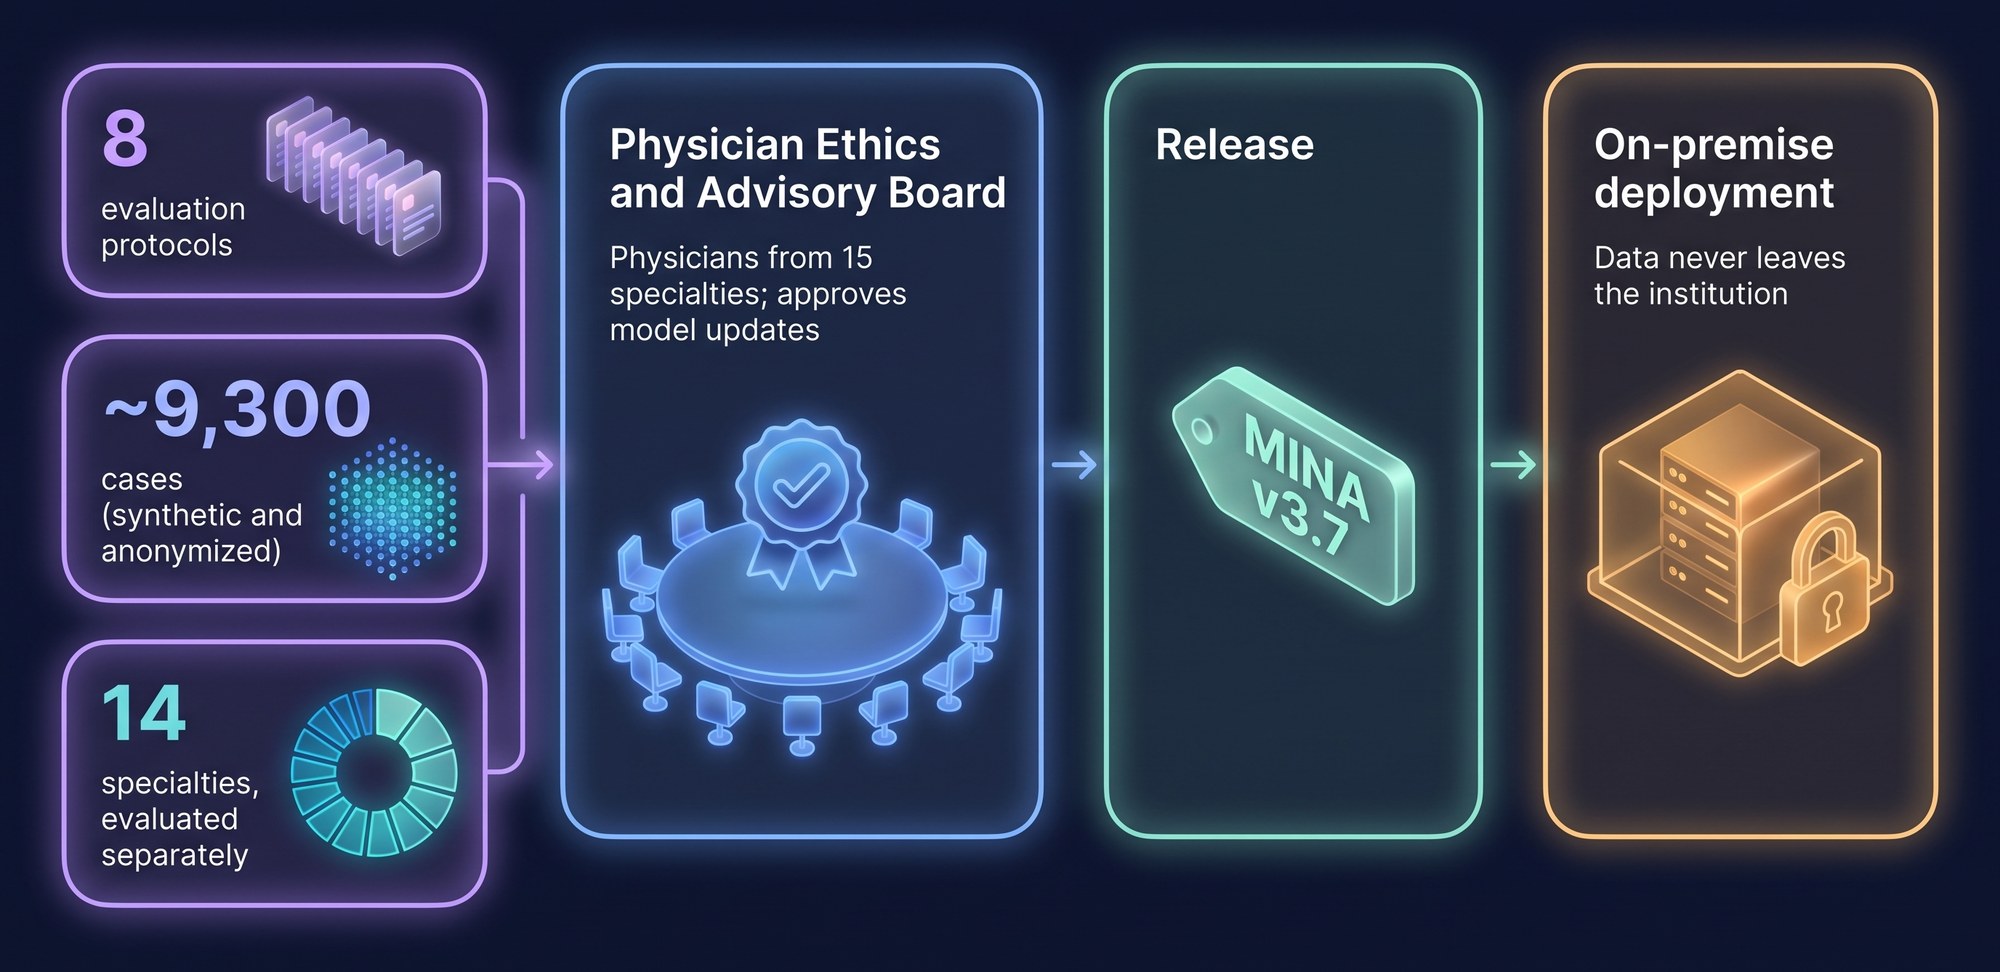
MINA v3.7 is the latest version of the clinical decision-support model developed for Turkish clinical practice. Five LoRA expertise adapters and three cross-cutting capabilities (safety, Turkish NLU, operational) were evaluated separately across 14 clinical specialties and sub-specialties.
Highlight results
Comparative performance
The table lists the primary metrics for each task. The blue column shows MINA v3.7, and a green outline indicates that the target was met.
| LoRA / Task | Metric | Target | MINA v3.5 | MINA v3.6 | MINA v3.7 | LLM-A | LLM-B | LLM-C |
|---|---|---|---|---|---|---|---|---|
| ICD-10 Coding | Top-1 Accuracy | ≥ 0.85 | 74% | 81% | 87% | 79% | 81% | 74% |
| ICD-10 Coding | Top-3 Accuracy | ≥ 0.95 | 88% | 93% | 96% | 91% | 92% | 88% |
| ICD-10 Coding | Hierarchical F1 | ≥ 0.90 | 83% | 88% | 92% | 88% | 89% | 85% |
| Discharge Summary | Slot F1 (micro) | ≥ 0.88 | 80% | 85% | 89% | 86% | 87% | 82% |
| Discharge Summary | Hallucinated sentences | ≤ 0.02 | 2.2% | 1.6% | 1.2% | 1.8% | 1.4% | 2.5% |
| Fraud / Policy | Fraud AUC-ROC | ≥ 0.92 | 86% | 89% | 93% | 85% | 87% | 81% |
| Fraud / Policy | Rejection Risk AUC | ≥ 0.90 | 83% | 87% | 91% | 82% | 84% | 78% |
| Fraud / Policy | Coverage Accuracy | ≥ 0.94 | 90% | 92% | 95% | 86% | 89% | 83% |
| SUT Compliance | Decision Accuracy | ≥ 0.90 | 82% | 86% | 91% | 71% | 75% | 65% |
| SUT Compliance | Clause MRR | ≥ 0.88 | 79% | 85% | 89% | 57% | 61% | 48% |
| SUT Compliance | Citation Hallucination | ≤ 0.005 | 0.8% | 0.5% | 0.3% | 4.5% | 2.8% | 6% |
| Clinical Decision | DDx Top-3 Accuracy | ≥ 0.92 | 85% | 89% | 93% | 91% | 93% | 89% |
| Clinical Decision | Plan–Expert Agreement | ≥ 0.82 | 77% | 81% | 84% | 82% | 85% | 79% |
| Clinical Decision | Contraindication Recall | ≥ 0.92 | 87% | 90% | 93% | 89% | 91% | 86% |
| Safety | Clinically Critical Hallucination | ≤ 0.005 | 0.8% | 0.5% | 0.3% | 1.1% | 0.6% | 1.5% |
| Safety | Clinical Trap Detection | ≥ 0.95 | 89% | 93% | 96% | 83% | 88% | 76% |
| Turkish NLU | Lay-Language Accuracy | ≥ 0.92 | 82% | 88% | 93% | 78% | 81% | 74% |
| Turkish NLU | Regional Dialect | ≥ 0.85 | 75% | 82% | 88% | 57% | 63% | 49% |
Version-over-version progress
The bars below show how the primary metrics improved across v3.5 → v3.6 → v3.7 on a fixed test set.
Documents
Detailed findings, full benchmark tables and methodology are in these white papers. Because they contain competitive comparisons, they are not published publicly; they are provided to organizations on request under a confidentiality agreement (NDA).
Evaluate MINA v3.7
in your own workflows
Through a POC, we can examine with you how MINA works in your clinical and administrative workflow.
POC Request